Increasing conversionswith AI Autocomplete
Current
- Type a search
- Browse 20 results
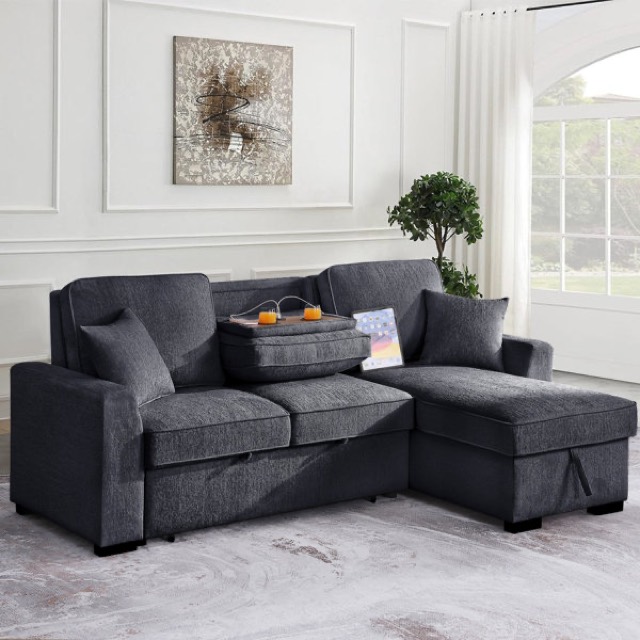
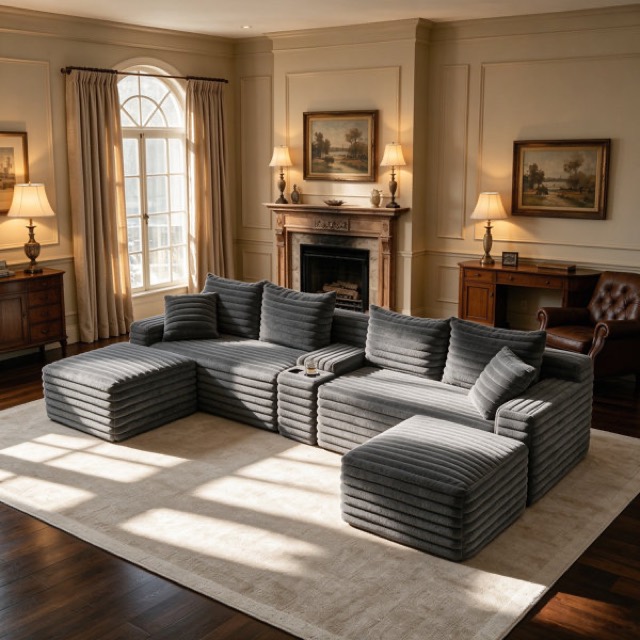
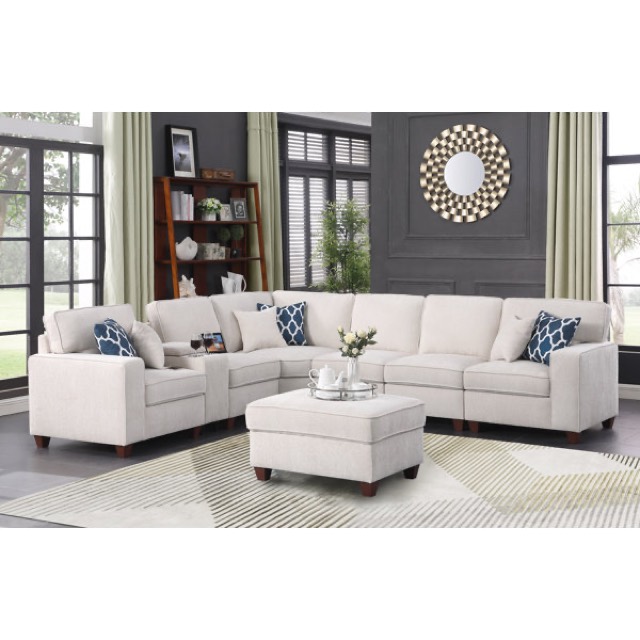
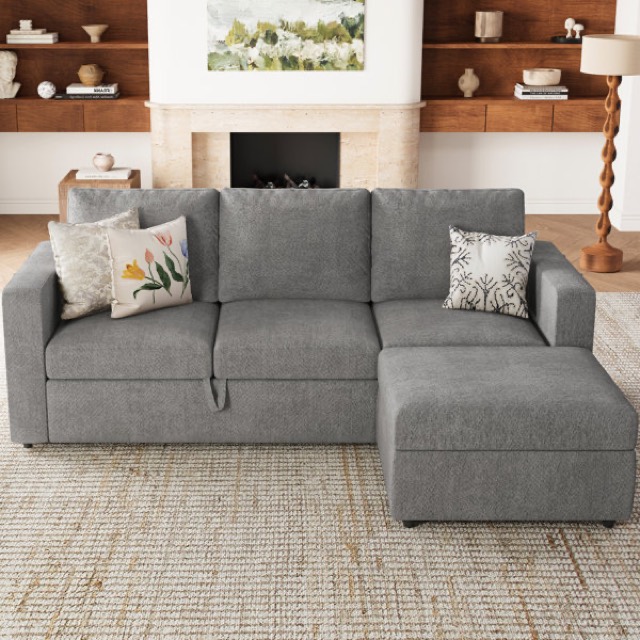
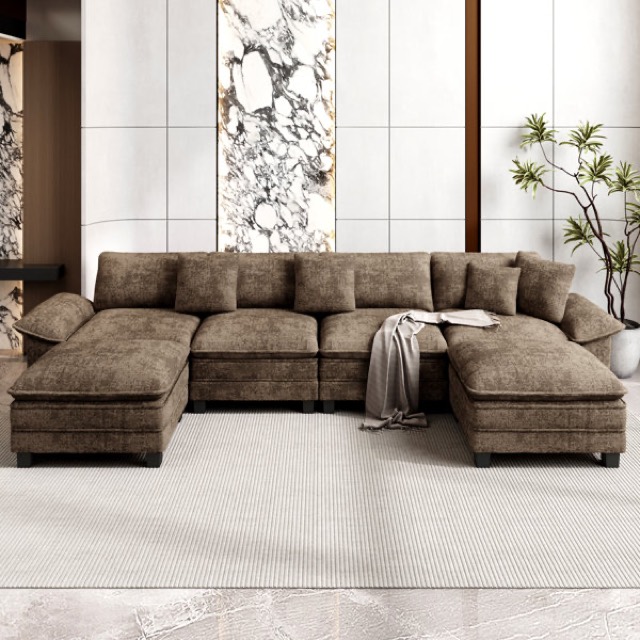
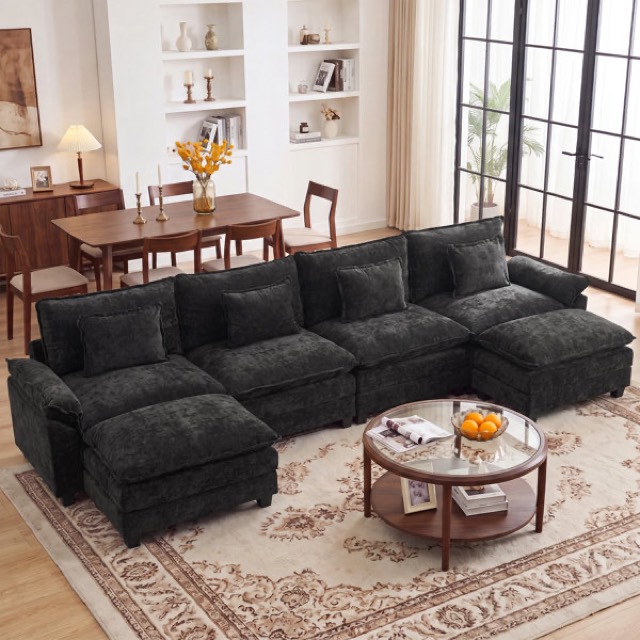
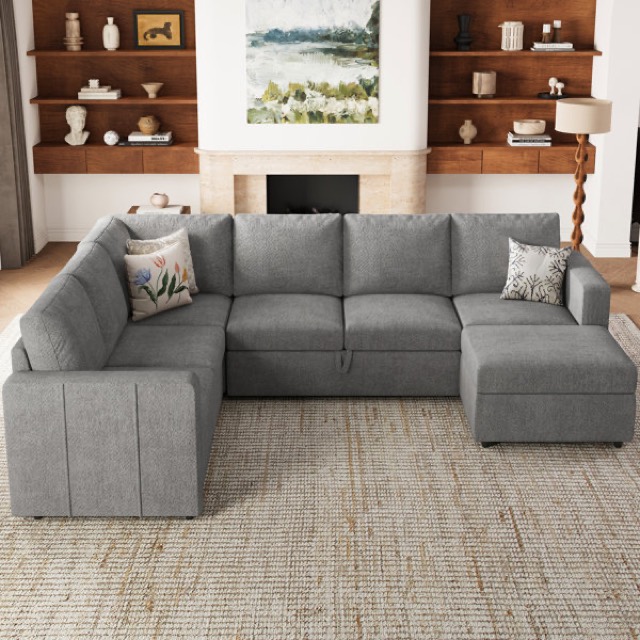
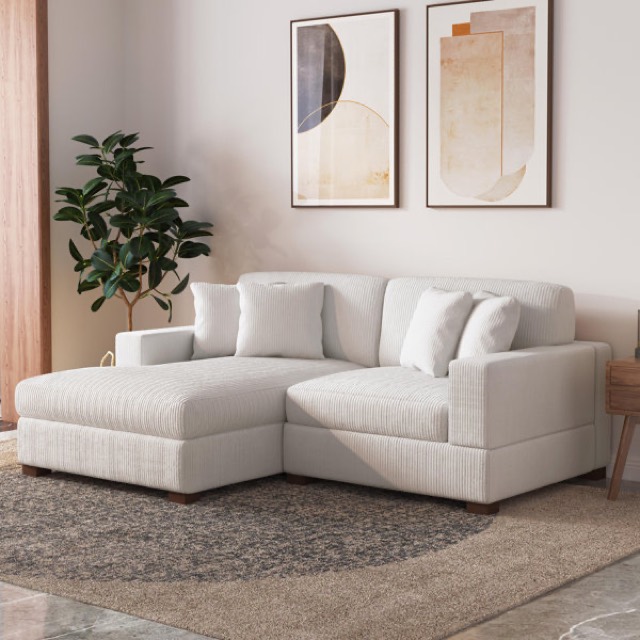
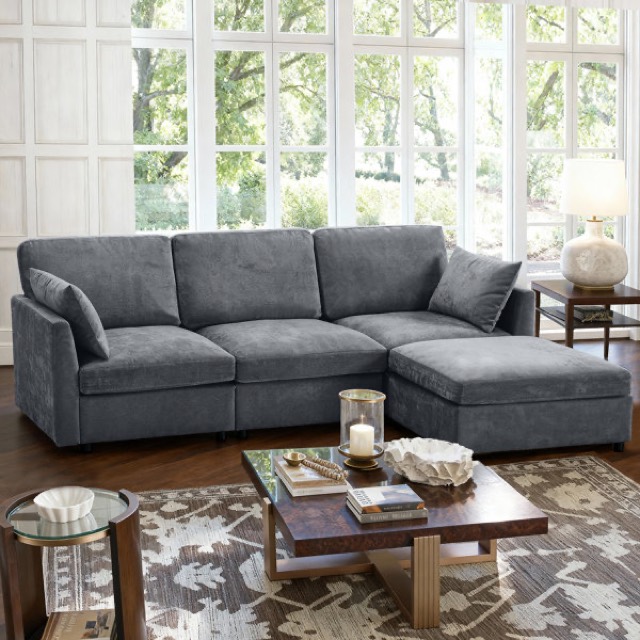
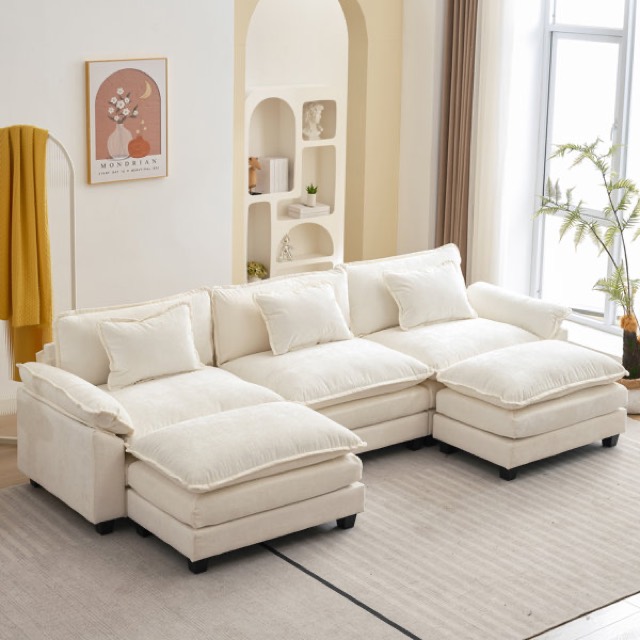
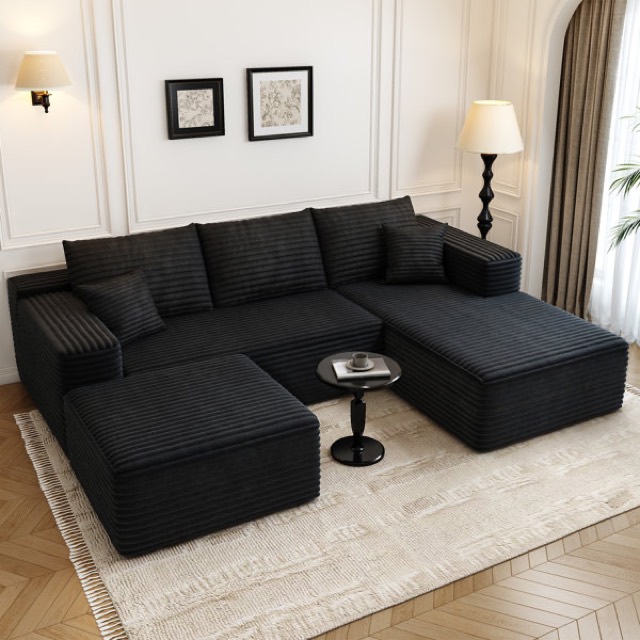
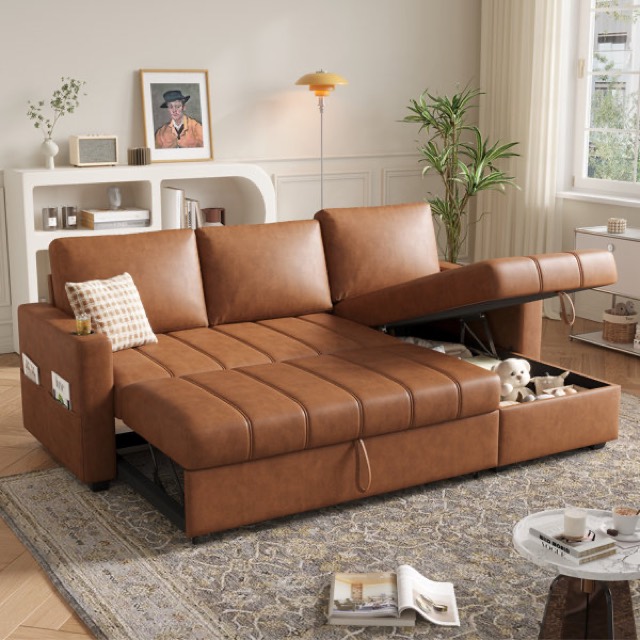
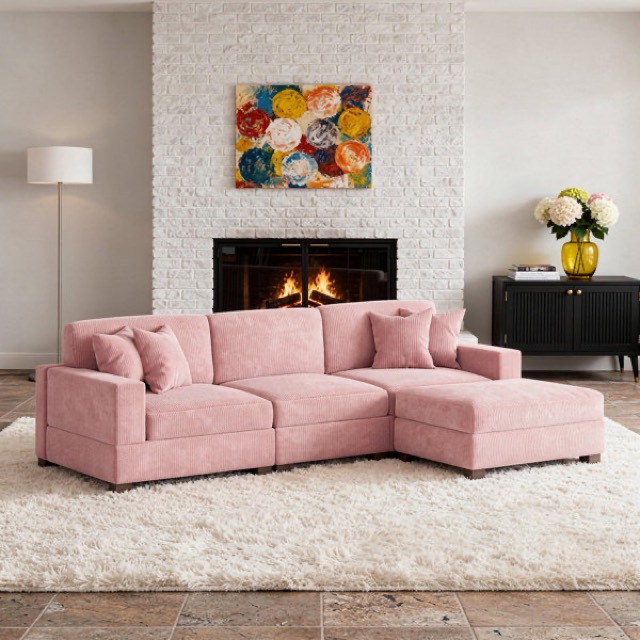
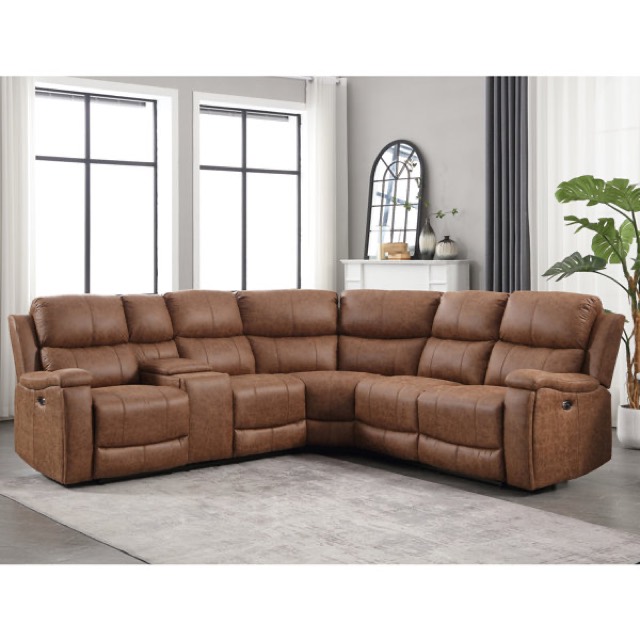
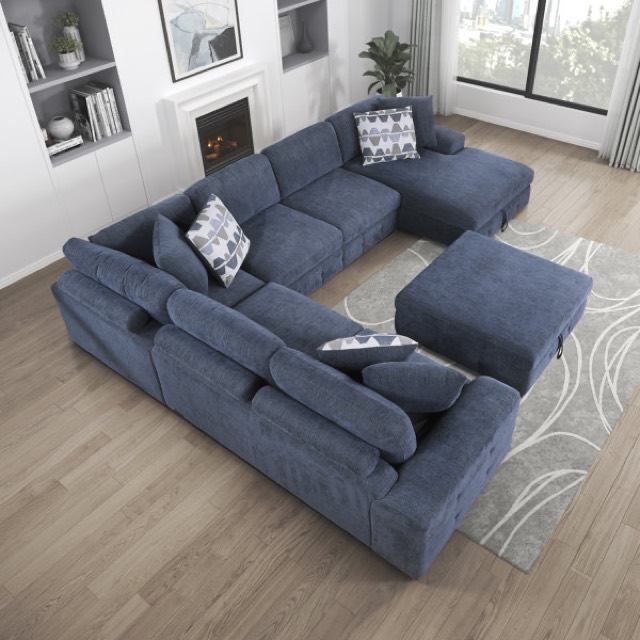
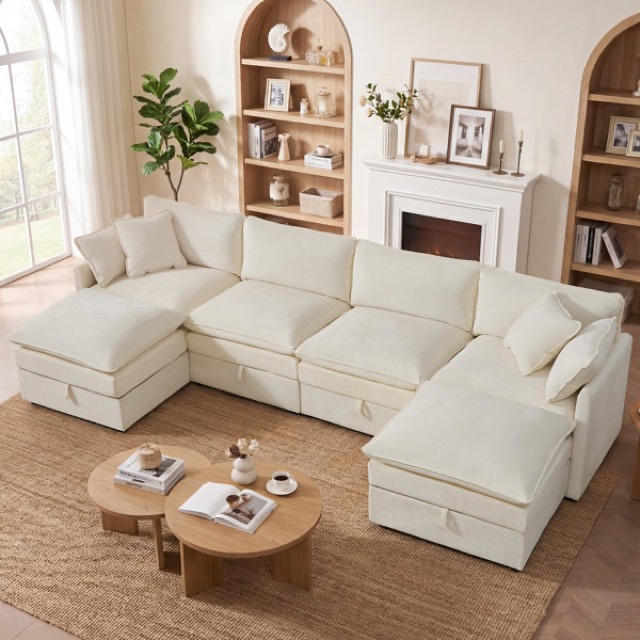
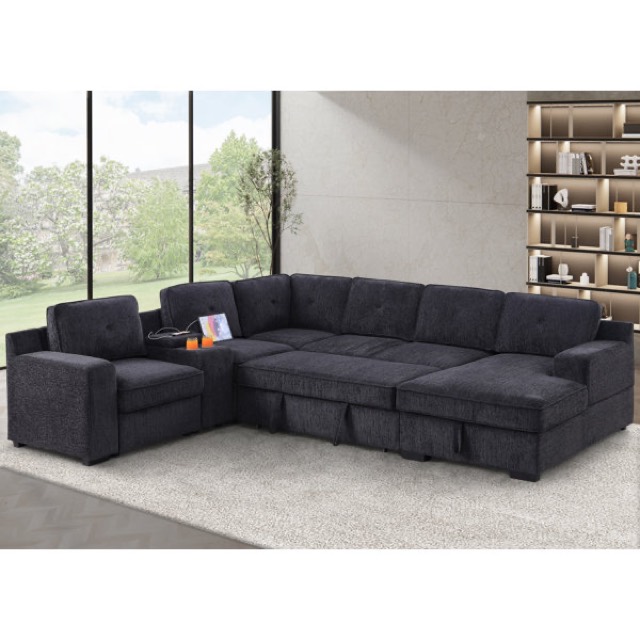
- Search a few words
- Compare sofas
- Add to cart
with AI Autocomplete
- Describe what you want
- Find your best matches
- Describe what fits
- Your best matches
- Add to cart
Connected to your catalogue
Better search = more shoppers finding the piece that fits.
The perfect sofa is more than a style. AI Autocomplete helps shoppers describe the fabric, features and price they have in mind, then passes that complete request to Wayfair’s existing search.
Your Wayfair catalogue
AI Autocomplete choices
FabricChenilleFeatureSleeper bedPriceUnder $1,500Your own data becomes the vocabulary people use to describe the sofa they want.
How it works
Quick to add. Works with the search box and data you already have.
01
Connect your data
Give AI Autocomplete the attributes already attached to every sofa.
02
Guide people as they type
Predict the detail that matters next and show relevant choices inside the search box.
03
Send a richer query to search
Pass the completed text and selected attributes into the backend you already use.
AI Autocomplete works with your search provider.
It only takes five minutes to set up.
- Your existing search
- Algolia
- Custom search backend
The SDK
What is the AI Autocomplete SDK?
AI Autocomplete supercharges your text box. It is an SDK you drop into the search box or prompt box you already have, and it starts guiding people through what they actually meant.
The goal of AI Autocomplete is to hand a more complete phrase to the next step of your stack (your search provider or agent). It is powered by an intent layer: an action engine that pairs the reasoning of an LLM with detection that lands in 150 to 200 ms, so the guidance appears while someone is still typing rather than after they submit.
Drops into the box you have
No migration and no replatform. Your search, your models and your pipeline stay exactly where they are.
Completes the request, not the phrase
Ordinary autocomplete finishes a word. This resolves the attributes the person never said out loud, inside the box, before submit.
150 to 200 ms detection
Fast enough to keep up with typing, so the help arrives in the moment it is useful rather than a beat too late.